- 152 Actual Exam Questions
- Compatible with all Devices
- Printable Format
- No Download Limits
- 90 Days Free Updates
Get All Salesforce Certified MuleSoft Platform Architect Exam Questions with Validated Answers
| Vendor: | Salesforce |
|---|---|
| Exam Code: | MuleSoft-Platform-Architect-I |
| Exam Name: | Salesforce Certified MuleSoft Platform Architect |
| Exam Questions: | 152 |
| Last Updated: | October 6, 2026 |
| Related Certifications: | Salesforce Architect |
| Exam Tags: | Intermediate Salesforce Enterprise ArchitectsSalesforce Solution Architects |
Looking for a hassle-free way to pass the Salesforce Certified MuleSoft Platform Architect exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Salesforce certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!
DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Salesforce MuleSoft-Platform-Architect-I exam questions give you the knowledge and confidence needed to succeed on the first attempt.
Train with our Salesforce MuleSoft-Platform-Architect-I exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.
Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Salesforce MuleSoft-Platform-Architect-I exam, we’ll refund your payment within 24 hours no questions asked.
Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Salesforce MuleSoft-Platform-Architect-I exam dumps today and achieve your certification effortlessly!
Your team is deploying a new API implementation to CloudHub that processes real-time payment transactions. The implementation requires temporary storage of transaction state between orchestration steps, must support failover across multiple regions for high availability, and expects peak traffic of 10,000 requests per minute. You are evaluating whether to use CloudHub Shared or Dedicated Load Balancer, how many workers to allocate, and which data persistence option to use for transaction state.
Which combination of decisions best meets the stated requirements while optimizing cost and resilience?
The correct answer balances resilience, cost, and functional requirements. The CloudHub Shared Load Balancer is sufficient for most workloads and is more cost-effective than Dedicated. Deploying 2–4 vCore workers across multiple regions provides failover and distributes load to handle 10,000 RPS. Object Store is the appropriate choice for temporary transaction state because it is persistent, survives worker restarts, and is optimized for high-throughput scenarios in CloudHub.
Option 2 is problematic: a single 4 vCore worker creates a single point of failure, and in-memory caching is lost on worker restart—inappropriate for transaction processing. Option 3 uses insufficient worker capacity (1 vCore cannot handle 10,000 RPS) and single-region deployment eliminates failover; Java HashMaps are not appropriate for persistent transaction state. Option 4 over-provisions resources (8 vCore workers across four regions is excessive for the stated load) and the Dedicated Load Balancer is unnecessary expense for this use case. Option 5 adds latency and complexity by requiring backend round-trips for state retrieval, defeating the purpose of intermediate storage.
A large lending company has developed an API to unlock data from a database server and web server. The API has been deployed to Anypoint Virtual Private Cloud
(VPC) on CloudHub 1.0.
The database server and web server are in the customer's secure network and are not accessible through the public internet. The database server is in the customer's AWS
VPC, whereas the web server is in the customer's on-premises corporate data center.
How can access be enabled for the API to connect with the database server and the web server?
Scenario Overview:
The API resides in Anypoint Virtual Private Cloud (VPC) on CloudHub 1.0, where it requires connectivity to both an AWS-hosted database server and an on-premises web server.
Both servers are isolated from the public internet: the database server is within the customer's AWS VPC, and the web server is within the customer's on-premises corporate data center.
Connectivity Requirements:
To connect to the AWS database server from the API in Anypoint VPC, VPC peering is ideal. This would allow a private network connection between the MuleSoft Anypoint VPC and the customer's AWS VPC, enabling secure, direct access to the database.
To connect to the on-premises web server, a VPN tunnel is suitable. This would establish a secure, encrypted connection from the Anypoint VPC to the customer's corporate data center, allowing secure data flow between the API and the on-premises web server.
Analysis of Options:
Option A (Correct Answer): Setting up VPC peering with AWS VPC enables private network connectivity with the database server, while a VPN tunnel to the on-premises data center allows secure access to the web server. This combination meets the requirements for secure, controlled access to both resources.
Option B: VPC peering alone would not suffice because it does not support a connection from the Anypoint VPC directly to an on-premises network. A VPN is necessary for on-premises access.
Option C: Setting up a transit gateway would provide connectivity within AWS but would not enable direct connectivity from CloudHub to the on-premises network.
Option D: VPC peering with the on-premises network is not possible because VPC peering is typically used to connect two VPCs, not a VPC with an on-premises network.
Conclusion:
Option A is the correct choice, as it provides a complete solution by using VPC peering for AWS VPC connectivity and a VPN tunnel for secure on-premises connectivity. This setup aligns with Anypoint Platform best practices for connecting Anypoint VPCs to both AWS-hosted and on-premises systems, ensuring secure, controlled access to both the database and web server.
For more detailed reference, MuleSoft documentation on Anypoint VPC peering and VPN connectivity provides additional context on best practices for setting up these connections within a hybrid network infrastructure.
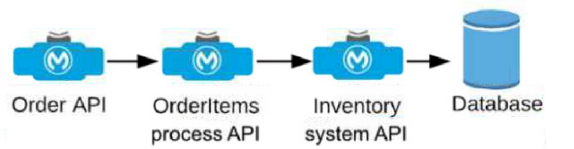
An Order API triggers a sequence of other API calls to look up details of an order's items in a back-end inventory database. The Order API calls the OrderItems process API, which calls the Inventory system API. The Inventory system API performs database operations in the back-end inventory database.
The network connection between the Inventory system API and the database is known to be unreliable and hang at unpredictable times.
Where should a two-second timeout be configured in the API processing sequence so that the Order API never waits more than two seconds for a response from the Orderltems process API?

Understanding the API Flow and Timeout Requirement:
The Order API initiates a call to the OrderItems process API, which in turn calls the Inventory system API to fetch details from the inventory database.
The requirement specifies that the Order API should not wait more than two seconds for a response from the OrderItems process API, even if there are delays further down the chain (between Inventory system API and the database).
Choosing the Appropriate Timeout Location:
Setting the timeout at the OrderItems process API level ensures that if the Inventory system API takes longer than two seconds to respond, the OrderItems process API will terminate the request and send a timeout response back to the Order API. This prevents the Order API from waiting indefinitely due to the unreliable connection to the database.
If the timeout were set in the Inventory system API or database, it would not help the Order API directly, as the OrderItems process API would still be waiting for a response.
Detailed Analysis of Each Option:
Option A (Correct Answer): Setting the timeout in the OrderItems process API allows it to control how long it waits for a response from the Inventory system API. If the Inventory system API does not respond within two seconds, the OrderItems process API can terminate the call and return a timeout response to the Order API, meeting the requirement.
Option B: Setting the timeout in the Order API would not limit the wait time at the OrderItems process API level, meaning the OrderItems process API could still wait indefinitely for the Inventory system API, leading to a longer delay.
Option C: Setting the timeout in the Inventory system API only affects the connection to the database and does not influence how long the OrderItems process API waits for the Inventory system API's response.
Option D: Setting a timeout in the database is not feasible in this context since database timeouts are typically configured for database operations and would not directly control the API response times in the overall API chain.
Conclusion:
Option A is the best choice, as it ensures that the OrderItems process API does not hold the Order API longer than the required two seconds, even if the downstream connection to the database hangs. This configuration aligns with MuleSoft best practices for setting timeouts in API orchestration to manage dependencies and prevent delays across a chain of API calls.
For additional information on timeout settings, refer to MuleSoft documentation on handling timeouts and API orchestration best practices.
An API client calls one method from an existing API implementation. The API implementation is later updated. What change to the API implementation would require the API client's invocation logic to also be updated?
Correct Answe r: When a new required field is added to the method called by the API client
*****************************************
>> Generally, the logic on API clients need to be updated when the API contract breaks.
>> When a new method or a child method is added to an API , the API client does not break as it can still continue to use its existing method. So these two options are out.
>> We are left for two more where 'datatype of the response if changed' and 'a new required field is added'.
>> Changing the datatype of the response does break the API contract. However, the question is insisting on the 'invocation' logic and not about the response handling logic. The API client can still invoke the API successfully and receive the response but the response will have a different datatype for some field.
>> Adding a new required field will break the API's invocation contract. When adding a new required field, the API contract breaks the RAML or API spec agreement that the API client/API consumer and API provider has between them. So this requires the API client invocation logic to also be updated.
What is a typical result of using a fine-grained rather than a coarse-grained API deployment model to implement a given business process?
Correct Answe r: A higher number of discoverable API-related assets in the application network.
*****************************************
>> We do NOT get faster response times in fine-grained approach when compared to coarse-grained approach.
>> In fact, we get faster response times from a network having coarse-grained APIs compared to a network having fine-grained APIs model. The reasons are below.
Fine-grained approach:
1. will have more APIs compared to coarse-grained
2. So, more orchestration needs to be done to achieve a functionality in business process.
3. Which means, lots of API calls to be made. So, more connections will needs to be established. So, obviously more hops, more network i/o, more number of integration points compared to coarse-grained approach where fewer APIs with bulk functionality embedded in them.
4. That is why, because of all these extra hops and added latencies, fine-grained approach will have bit more response times compared to coarse-grained.
5. Not only added latencies and connections, there will be more resources used up in fine-grained approach due to more number of APIs.
That's why, fine-grained APIs are good in a way to expose more number of resuable assets in your network and make them discoverable. However, needs more maintenance, taking care of integration points, connections, resources with a little compromise w.r.t network hops and response times.
Security & Privacy
Satisfied Customers
Committed Service
Money Back Guranteed