- 63 Actual Exam Questions
- Compatible with all Devices
- Printable Format
- No Download Limits
- 90 Days Free Updates
Get All Marketing Cloud Intelligence Accredited Professional Exam Questions with Validated Answers
| Vendor: | Salesforce |
|---|---|
| Exam Code: | Marketing-Cloud-Intelligence |
| Exam Name: | Marketing Cloud Intelligence Accredited Professional |
| Exam Questions: | 63 |
| Last Updated: | October 7, 2026 |
| Related Certifications: | Accredited Professional |
| Exam Tags: | Marketing Cloud, Customer relationship management (CRM), Cloud computing Professional Salesforce marketing professionals |
Looking for a hassle-free way to pass the Salesforce Marketing Cloud Intelligence Accredited Professional exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Salesforce certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!
DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Salesforce Marketing-Cloud-Intelligence exam questions give you the knowledge and confidence needed to succeed on the first attempt.
Train with our Salesforce Marketing-Cloud-Intelligence exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.
Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Salesforce Marketing-Cloud-Intelligence exam, we’ll refund your payment within 24 hours no questions asked.
Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Salesforce Marketing-Cloud-Intelligence exam dumps today and achieve your certification effortlessly!
What is the relationship between "Media Buy Key" and "Creative Key?
In Marketing Cloud Intelligence, the 'Media Buy Key' is typically associated with the purchase details of a media campaign, such as the platform, audience, and budget. The 'Creative Key' relates to the specific creative asset used within a campaign, like an image, video, or text. A single media buy can have multiple creative variations to test performance or to target different audiences, leading to a one-to-many relationship.
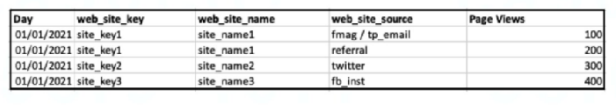
The following file was uploaded into Marketing Cloud Intelligence as a generic dataset type:

The mapping is as follows:
Day --- Day
Web_site_source --- Main Generic Entity Attribute 01
Page Views --- Generic Metric 1
*Note that 'web_site_key' and 'web_site_name' are NOT mapped.
How many rows will be stored in Marketing Cloud Intelligence after the above file is ingested?
In Marketing Cloud Intelligence, when a file is uploaded as a generic dataset type and mapped accordingly, each unique combination of the mapped fields results in a separate row in the database. The file in question has been mapped with 'Day' to 'Day', 'Web_site_source' to 'Main Generic Entity Attribute 01', and 'Page Views' to 'Generic Metric 1'. The 'web_site_key' and 'web_site_name' are not mapped and thus, won't affect the row count.
Since there are 4 unique combinations of the mapped fields in the uploaded file (each day and source combination is unique), Marketing Cloud Intelligence will store 4 rows after ingestion, corresponding to each unique combination of 'Day' and 'Web_site_source'.
An implementation engineer is requested to extract the second position
of the Campaign Name values.
The Campaign values consist of multiple delimiter types, as can be
seen in the following example:
Campaign Name: Ad15X2w&Delux_wal90
Desired value: Delux
Which three harmonization methods will achieve the desired outcome?
To extract specific elements from a string in Marketing Cloud Intelligence, such as the second position of a Campaign Name with multiple delimiters, several harmonization methods can be employed:
Calculated Dimensions: These allow for the creation of custom dimensions using expressions or formulas that manipulate existing data. A calculated dimension can be designed to parse and extract segments of a string based on delimiters.
Patterns: This method involves defining a pattern or regex (regular expression) that matches and isolates the desired portion of the string. Patterns are highly effective for strings with complex structures and varying delimiter types.
Mapping Formula: Similar to calculated dimensions, mapping formulas provide a way to apply a transformation or extraction rule to data fields directly within data streams, enabling targeted data extraction like the desired 'Delux' from the Campaign Name.
These methods enable the implementation engineer to accurately segment and extract the needed data from complex string fields efficiently.
An implementation engineer has been provided with 4 different source files: 03m 16s
1. Twitter Ads
2. Creative Classification
3. Placement Classification
4, Campaign Category Classification
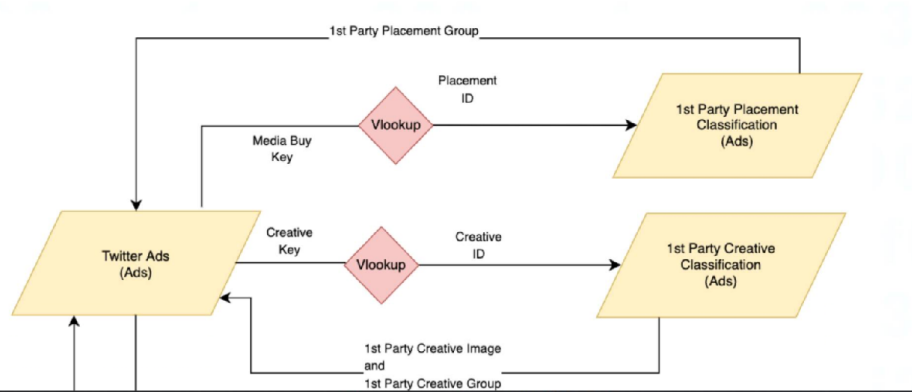
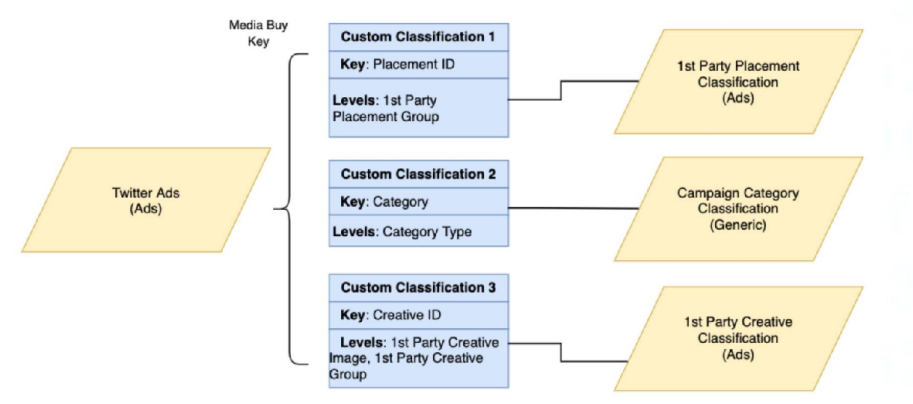
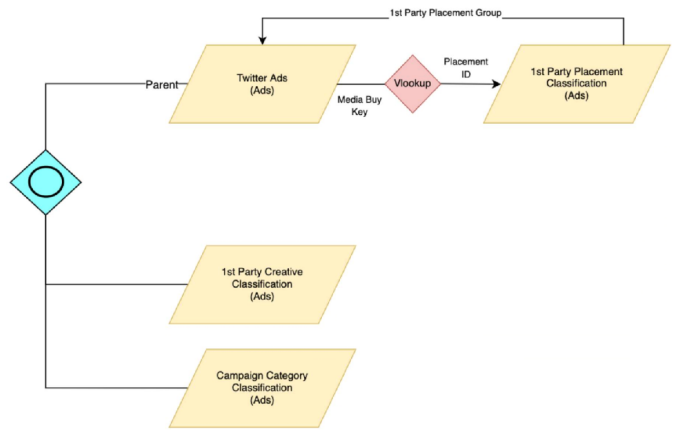
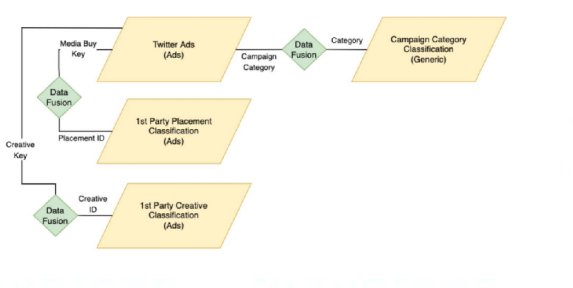
The main source is Twitter Ads (which includes various fields and KPIs), and the rest are classification files that connect to Twitter Ads and enrich different fields within it.
The connections between the files are described as follows:
1st Party Creative Classification
File structure/headers:

Creative ID --- links back to Creative Key (Twitter Ads)
1st Party Placement Classification &
File structure/headers:

Category --- links back to Campaign Category (Twitter Ads)
Which proposed solution meets the client's requirements for the above use case?
A)

B)

C)

D)

For the given use case, where the Twitter Ads data stream needs to be enriched with classifications from three other sources, the correct implementation would involve creating links between the various fields across these files.
Option A is correct because it shows the correct usage of the fields from the classification files:
'Creative ID' in the Creative Classification file is linked to the 'Creative Key' in the Twitter Ads data, allowing for enrichment with creative details.
'Placement ID' in the Placement Classification file is linked to a corresponding field in the Twitter Ads data, allowing for placement details to be added.
'Category' in the Campaign Category Classification file is linked back to 'Campaign Category' in the Twitter Ads data, thus enriching the campaign data with the correct categories.
This configuration correctly uses VLOOKUP to enrich the Twitter Ads data stream with additional details from the classification files, aligning with best practices for data integration and enrichment in Marketing Cloud Intelligence.
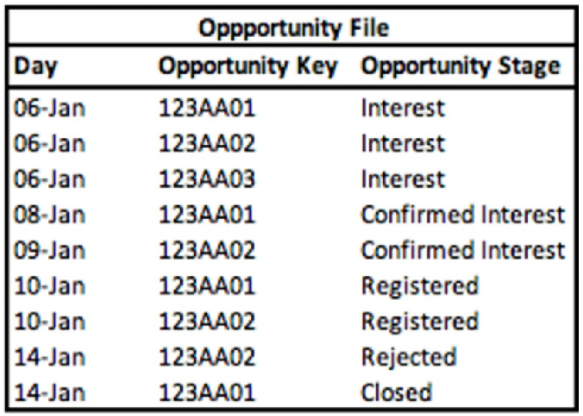
A technical architect is provided with the logic and Opportunity file shown below:
The opportunity status logic is as follows:
For the opportunity stages ''Interest'', ''Confirmed Interest'' and ''Registered'', the status should be ''Open''.
For the opportunity stage ''Closed'', the opportunity status should be closed
Otherwise, return null for the opportunity status
Given the above file and logic and assuming that the file is mapped in a GENERIC data stream type with the following mapping:
''Day'' --- Standard ''Day'' field
''Opportunity Key'' > Main Generic Entity Key
''Opportunity Stage'' --- Generic Entity Key 2
''Opportunity Count'' --- Generic Custom Metric
A pivot table was created to present the count of opportunities in each stage. The pivot table is filtered on January (entire month). What is the number of opportunities in the Interest stage?
Based on the Opportunity file, the Opportunity Stage of 'Interest' occurs 3 times across unique Opportunity Keys. Since the pivot table is filtered to present the entire month of January and the Opportunity Stage 'Interest' is listed three times with different Opportunity Keys, the count of opportunities in the 'Interest' stage would be 3.
Security & Privacy
Satisfied Customers
Committed Service
Money Back Guranteed