Qlik QSDA2024 Exam Dumps

Get All Qlik Sense Data Architect Certification Exam - 2024 Exam Questions with Validated Answers

QSDA2024 Pack
Vendor: Qlik
Exam Code: QSDA2024
Exam Name: Qlik Sense Data Architect Certification Exam - 2024
Exam Questions: 50
Last Updated: October 7, 2026
Related Certifications: Qlik Sense
Exam Tags: Associate Qlik Sense Data architectsQlik Sense Data Analysts
Gurantee
  • 24/7 customer support
  • Unlimited Downloads
  • 90 Days Free Updates
  • 10,000+ Satisfied Customers
  • 100% Refund Policy
  • Instantly Available for Download after Purchase

Get Full Access to Qlik QSDA2024 questions & answers in the format that suits you best

PDF Version

$40.00
$24.00
  • 50 Actual Exam Questions
  • Compatible with all Devices
  • Printable Format
  • No Download Limits
  • 90 Days Free Updates

Discount Offer (Bundle pack)

$80.00
$48.00
  • Discount Offer
  • 50 Actual Exam Questions
  • Both PDF & Online Practice Test
  • Free 90 Days Updates
  • No Download Limits
  • No Practice Limits
  • 24/7 Customer Support

Online Practice Test

$30.00
$18.00
  • 50 Actual Exam Questions
  • Actual Exam Environment
  • 90 Days Free Updates
  • Browser Based Software
  • Compatibility:
    supported Browsers

Pass Your Qlik QSDA2024 Certification Exam Easily!

Looking for a hassle-free way to pass the Qlik Sense Data Architect Certification Exam - 2024 exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Qlik certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!

DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Qlik QSDA2024 exam questions give you the knowledge and confidence needed to succeed on the first attempt.

Train with our Qlik QSDA2024 exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.

Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Qlik QSDA2024 exam, we’ll refund your payment within 24 hours no questions asked.
 

Why Choose DumpsProvider for Your Qlik QSDA2024 Exam Prep?

  • Verified & Up-to-Date Materials: Our Qlik experts carefully craft every question to match the latest Qlik exam topics.
  • Free 90-Day Updates: Stay ahead with free updates for three months to keep your questions & answers up to date.
  • 24/7 Customer Support: Get instant help via live chat or email whenever you have questions about our Qlik QSDA2024 exam dumps.

Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Qlik QSDA2024 exam dumps today and achieve your certification effortlessly!

Free Qlik QSDA2024 Exam Actual Questions

Question No. 1

A data architect inherits an app that takes too long to load and overruns the data load window.

The app pulls all records (new and historical) from three large databases. The reload process puts a heavy load on the source database servers. All of the data is required for analysis.

What should the data architect do?

Show Answer Hide Answer
Correct Answer: C

The scenario describes an app that is experiencing long load times due to the need to pull all records, both new and historical, from three large databases. This situation puts a strain on both the Qlik environment and the source databases. Given that all data is required for analysis, a full reload each time can be inefficient and resource-intensive.

Implementing incremental load is a widely recommended approach in such cases. Incremental loading allows you to load only new or changed data since the last reload, rather than reloading all the data every time. This significantly reduces the time and resources required for reloading, as only a subset of the data needs to be processed during each reload. QVD (QlikView Data) files are typically used to store the historical data, while only the new or updated records are fetched from the source databases.

This approach would help:

Reduce the load on the source databases.

Shorten the data reload window.

Maintain historical data efficiently while ensuring that all new data is captured.


Question No. 2

Refer to the exhibit.

Refer to the exhibit.

A data architect needs to create a data model for a new app. Users must be able to see:

* Total sales for each customer

* Total sales for a given state

* Customers that have not had any sales

* Names of salesperson and regional account managers

* Total number of sales by date

Which steps should the data architect perform to meet these requirements?

Which steps should the data architect perform to meet these requirements?

Show Answer Hide Answer
Correct Answer: C

In the provided scenario, the data architect needs to create a data model that supports various analyses, including total sales for each customer, total sales by state, identifying customers with no sales, and displaying the names of salespersons and regional account managers.

Here's why Option C is the correct choice:

Loading the Sales Table: The Sales table contains key information related to sales transactions, including SaleID, CustomerID, Amount, SaleDate, SalesPersonID, and RegionalAcctMgrID. This table must be loaded first as it will be central to the analysis.

Loading the Customers Table: The Customers table includes customer details such as CustID, CustName, Address, City, State, and Zip. Loading this table and linking it to the Sales table via the CustomerID field allows you to perform analyses such as total sales per customer and total sales by state. Importantly, loading the customers separately will also allow the identification of customers without any sales.

Loading the Employees Table Twice: The Employees table must be loaded twice because it is used to look up two different roles in the sales process: the SalesPersonID and the RegionalAcctMgrID. When loading the table twice:

The first instance of the Employees table will be used to map the SalesPersonID to EmployeeName.

The second instance will be used to map the RegionalAcctMgrID to EmployeeName.

Aliasing the EmployeeID field appropriately in each instance is crucial to prevent creating synthetic keys and to ensure the correct association with the roles in the sales process.

This approach ensures that the data model will correctly support all the required analyses, including identifying customers without sales, which is crucial for meeting the business requirements.

Option A and Option B propose using a mapping load and ApplyMap, which can complicate the model and does not directly address all the business requirements.

Option D involves aliasing fields in a way that could create unnecessary complexity and might not accurately reflect the relationships in the data.

Thus, Option C is the correct answer as it best meets the requirements while maintaining a clear and functional data model.


Question No. 3

Exhibit.

Refer to the exhibit.

A data architect is working on a Qlik Sense app the business has created to analyze the company orders and shipments.

To understand the table structure, the business has given the following summary:

* Every order creates a unique orderlD and an order date in the Orders table

* An order can contain one or more order lines one for each product ID in the order details table

* Products In the order are shipped (shipment date) as soon as they are ready and can be shipped separately

* The dates need to be analyzed separately by Year, Month, and Quarter

The data architect realizes the data model has issues that must be fixed. Which steps should the data architect perform?

Show Answer Hide Answer
Correct Answer: C

In the given data model, there are several issues related to table relationships and key fields that need to be addressed to create a functional and optimized data model. Here's how each step in the chosen solution (Option C) resolves these issues:

Create a key with OrderID and ProductID in the OrderDetails table and in the Shipments table:

By creating a composite key with OrderID and ProductID, you uniquely identify each line item in both the OrderDetails and Shipments tables. This step is crucial for ensuring that each product within an order is correctly associated with its respective shipment.

Delete the ShipmentID in the Orders table:

The ShipmentID in the Orders table is redundant because the Shipments table already captures this information at a more granular level (i.e., at the product level). Removing ShipmentID avoids potential circular references or synthetic keys.

Delete the ProductID and OrderID in the Shipments table:

After creating the composite key in step 1, the individual ProductID and OrderID fields in the Shipments table are no longer necessary for joins. Removing them reduces redundancy and simplifies the table structure.

Concatenate Orders and OrderDetails:

Concatenating Orders and OrderDetails into a single table creates a unified table that contains all necessary order-related information. This helps in simplifying the model and avoiding issues related to managing separate but related tables.

Create a link table using the MasterCalendar table and create a concatenated field between OrderDate and ShipmentDate:

A link table is created to associate the combined table with the MasterCalendar. By creating a concatenated field that combines OrderDate and ShipmentDate, you ensure that both dates are properly linked to the calendar, allowing for accurate time-based analysis.


Question No. 4

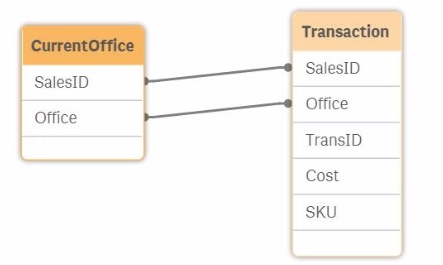
Exhibit

Refer to the exhibit.

The salesperson ID and the office to which the salesperson belongs is stored for each transaction. The data model also contains the current office for the salesperson. The current office of the salesperson and the office the salesperson was in when the transaction occurred must be visible. The current source table view of the model is shown. A data architect must resolve the synthetic key.

How should the data architect proceed?

Show Answer Hide Answer
Correct Answer: C

In the provided data model, both the CurrentOffice and Transaction tables contain the fields SalesID and Office. This leads to the creation of a synthetic key in Qlik Sense because of the two common fields between the two tables. A synthetic key is created automatically by Qlik Sense when two or more tables have two or more fields in common. While synthetic keys can be useful in some scenarios, they often lead to unwanted and unexpected results, so it's generally advisable to resolve them.

In this case, the goal is to have both the current office of the salesperson and the office where the transaction occurred visible in the data model. Here's how each option compares:

Option A: Comment out the Office in the Transaction table: This would remove the Office field from the Transaction table, which would prevent you from seeing which office the salesperson was in when the transaction occurred. This option does not meet the requirement.

Option B: Inner Join the Transaction table to the CurrentOffice table: Performing an inner join would merge the two tables based on the common SalesID and Office fields. However, this might result in a loss of data if there are sales records in the Transaction table that don't have a corresponding record in the CurrentOffice table or vice versa. This approach might also lead to unexpected results in your analysis.

Option C: Alias Office to CurrentOffice In the CurrentOffice table: By renaming the Office field in the CurrentOffice table to CurrentOffice, you prevent the synthetic key from being created. This allows you to differentiate between the salesperson's current office and the office where the transaction occurred. This approach maintains the integrity of your data and allows for clear analysis.

Option D: Force concatenation between the tables: Forcing concatenation would combine the rows of both tables into a single table. This would not solve the issue of distinguishing between the current office and the office at the time of the transaction, and it could lead to incorrect data associations.

Given these considerations, the best approach to resolve the synthetic key while fulfilling the requirement of having both the current office and the office at the time of the transaction visible is to Alias Office to CurrentOffice in the CurrentOffice table. This ensures that the data model will accurately represent both pieces of information without causing synthetic key issues.


Question No. 5

Exhibit.

While performing a data load from the source shown, the data architect notices it is NOT appropriate for the required analysis.

The data architect runs the following script to resolve this issue:

How many tables will this script create?

Show Answer Hide Answer
Correct Answer: D

In this scenario, the data architect is using a GENERIC LOAD statement in the script to handle the data structure provided. A GENERIC LOAD is used in Qlik Sense when you have data in a key-value pair structure and you want to transform it into a more traditional table structure, where each attribute becomes a column.

Given the input data table with three columns (Object, Attribute, Value), and the attributes in the Attribute field being either color, diameter, length, or width, the GENERIC LOAD will create separate tables based on the combinations of Object and each Attribute.

Here's how the GENERIC LOAD works:

For each unique object (circle, rectangle, square), the GENERIC LOAD creates separate tables based on the distinct values of the Attribute field.

Each of these tables will contain two fields: Object and the specific attribute (e.g., color, diameter, length, width).

Breakdown:

Table for circle:

Fields: Object, color, diameter

Table for rectangle:

Fields: Object, color, length, width

Table for square:

Fields: Object, color, length

Each distinct attribute (color, diameter, length, width) and object combination generates a separate table.

Final Count of Tables:

The script will create 6 separate tables: one for each unique combination of Object and Attribute.


Qlik Sense Documentation on Generic Load: Generic loads are used to pivot key-value pair data structures into multiple tables, where each key (in this case, the Attribute field values) forms a new column in its own table.

100%

Security & Privacy

10000+

Satisfied Customers

24/7

Committed Service

100%

Money Back Guranteed