- 142 Actual Exam Questions
- Compatible with all Devices
- Printable Format
- No Download Limits
- 90 Days Free Updates
Get All Implementing Data Engineering Solutions Using Microsoft Fabric Exam Questions with Validated Answers
| Vendor: | Microsoft |
|---|---|
| Exam Code: | DP-700 |
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Questions: | 142 |
| Last Updated: | October 9, 2026 |
| Related Certifications: | Fabric Data Engineer Associate |
| Exam Tags: | Data engineering, Data management Intermediate Level Microsoft Data Analysts and Engineers |
Looking for a hassle-free way to pass the Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Microsoft certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!
DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Microsoft DP-700 exam questions give you the knowledge and confidence needed to succeed on the first attempt.
Train with our Microsoft DP-700 exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.
Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Microsoft DP-700 exam, we’ll refund your payment within 24 hours no questions asked.
Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Microsoft DP-700 exam dumps today and achieve your certification effortlessly!
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
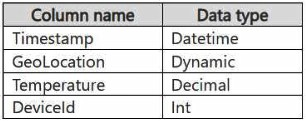
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
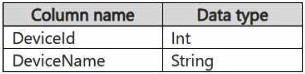
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
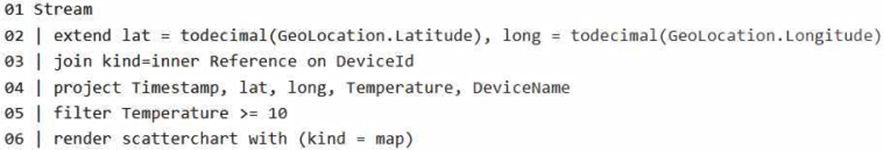
You need to reduce how long it takes to run the KQL queryset.
Solution: You add the make_list() function to the output columns.
Does this meet the goal?
Adding an aggregation like make_list() would require additional processing and memory, which could make the query slower.
You are monitoring a Fabric warehouse that supports a critical business dashboard used by executives daily. Over the past week, you've noticed that query performance has degraded gradually: queries that previously completed in 2 seconds now take 8-12 seconds. No schema changes have occurred, and data volume has grown only 5%. You need to identify the root cause and optimize performance. Which investigation approach is most appropriate?
The correct approach is to analyze execution plans and statistics to identify actual performance issues before taking action. Outdated statistics cause the query optimizer to make poor choices, and missing indexes are common causes of gradual degradation when data volume grows modestly. Investigation precedes optimization. Increasing SKU without diagnosis wastes cost (5% data growth doesn't justify tier increases). Dropping indexes doesn't improve performance when statistics are stale. Cache clearing and restarts are temporary and don't address root cause. Warehouses are appropriate for structured analytics and don't inherently degrade; the solution lies in query optimization. This tests monitoring and optimization competency.
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
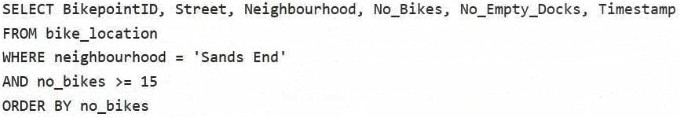
Solution: You use the following code segment:

Does this meet the goal?
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like:

What should you do to optimize the query experience for the business users?
You need to populate the MAR1 data in the bronze layer.
Which two types of activities should you include in the pipeline? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
MAR1 has seven entities, each accessible via a different API endpoint. A ForEach activity is required to iterate over these endpoints to fetch data from each one. It enables dynamic execution of API calls for each entity.
The Copy data activity is the primary mechanism to extract data from REST APIs and load it into the bronze layer in Delta format. It supports native connectors for REST APIs and Delta, minimizing development effort.
Security & Privacy
Satisfied Customers
Committed Service
Money Back Guranteed