- 74 Actual Exam Questions
- Compatible with all Devices
- Printable Format
- No Download Limits
- 90 Days Free Updates
Get All Databricks Certified Machine Learning Associate Exam Questions with Validated Answers
| Vendor: | Databricks |
|---|---|
| Exam Code: | Databricks-Machine-Learning-Associate |
| Exam Name: | Databricks Certified Machine Learning Associate Exam |
| Exam Questions: | 74 |
| Last Updated: | October 7, 2026 |
| Related Certifications: | Machine Learning Associate |
| Exam Tags: | Associate Data ScientistsMachine Learning Engineers |
Looking for a hassle-free way to pass the Databricks Certified Machine Learning Associate Exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Databricks certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!
DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Databricks-Machine-Learning-Associate exam questions give you the knowledge and confidence needed to succeed on the first attempt.
Train with our Databricks-Machine-Learning-Associate exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.
Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Databricks-Machine-Learning-Associate exam, we’ll refund your payment within 24 hours no questions asked.
Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Databricks-Machine-Learning-Associate exam dumps today and achieve your certification effortlessly!
A data scientist is wanting to explore the Spark DataFrame spark_df. The data scientist wants visual histograms displaying the distribution of numeric features to be included in the exploration.
Which of the following lines of code can the data scientist run to accomplish the task?
To display visual histograms and summaries of the numeric features in a Spark DataFrame, the Databricks utility function dbutils.data.summarize can be used. This function provides a comprehensive summary, including visual histograms.
Correct code:
dbutils.data.summarize(spark_df)
Other options like spark_df.describe() and spark_df.summary() provide textual statistical summaries but do not include visual histograms.
Databricks Utilities Documentation
A data scientist is performing hyperparameter tuning using an iterative optimization algorithm. Each evaluation of unique hyperparameter values is being trained on a single compute node. They are performing eight total evaluations across eight total compute nodes. While the accuracy of the model does vary over the eight evaluations, they notice there is no trend of improvement in the accuracy. The data scientist believes this is due to the parallelization of the tuning process.
Which change could the data scientist make to improve their model accuracy over the course of their tuning process?
The lack of improvement in model accuracy across evaluations suggests that the optimization algorithm might not be effectively exploring the hyperparameter space. Iterative optimization algorithms like Tree-structured Parzen Estimators (TPE) or Bayesian Optimization can adapt based on previous evaluations, guiding the search towards more promising regions of the hyperparameter space.
Changing the optimization algorithm can lead to better utilization of the information gathered during each evaluation, potentially improving the overall accuracy.
Hyperparameter Optimization with Hyperopt
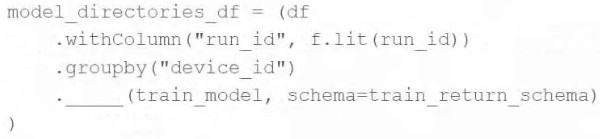
A machine learning engineer wants to parallelize the training of group-specific models using the Pandas Function API. They have developed the train_model function, and they want to apply it to each group of DataFrame df.
They have written the following incomplete code block:

Which of the following pieces of code can be used to fill in the above blank to complete the task?
The function mapInPandas in the PySpark DataFrame API allows for applying a function to each partition of the DataFrame. When working with grouped data, groupby followed by applyInPandas is the correct approach to apply a function to each group as a separate Pandas DataFrame. However, if the function should apply across each partition of the grouped data rather than on each individual group, mapInPandas would be utilized. Since the code snippet indicates the use of groupby, the intent seems to be to apply train_model on each group specifically, which aligns with applyInPandas. Thus, applyInPandas is a better fit to ensure that each group generated by groupby is processed through the train_model function, preserving the partitioning and grouping integrity.
Reference
A machine learning engineer has identified the best run from an MLflow Experiment. They have stored the run ID in the run_id variable and identified the logged model name as "model". They now want to register that model in the MLflow Model Registry with the name "best_model".
Which lines of code can they use to register the model associated with run_id to the MLflow Model Registry?
To register a model that has been identified by a specific run_id in the MLflow Model Registry, the appropriate line of code is:
mlflow.register_model(f'runs:/{run_id}/model', 'best_model')
This code correctly specifies the path to the model within the run (runs:/{run_id}/model) and registers it under the name 'best_model' in the Model Registry. This allows the model to be tracked, managed, and transitioned through different stages (e.g., Staging, Production) within the MLflow ecosystem.
Reference
MLflow documentation on model registry: https://www.mlflow.org/docs/latest/model-registry.html#registering-a-model
A data scientist has produced two models for a single machine learning problem. One of the models performs well when one of the features has a value of less than 5, and the other model performs well when the value of that feature is greater than or equal to 5. The data scientist decides to combine the two models into a single machine learning solution.
Which of the following terms is used to describe this combination of models?
Ensemble learning is a machine learning technique that involves combining several models to solve a particular problem. The scenario described fits the concept of ensemble learning, where two models, each performing well under different conditions, are combined to create a more robust model. This approach often leads to better performance as it combines the strengths of multiple models.
Reference
Introduction to Ensemble Learning: https://machinelearningmastery.com/ensemble-machine-learning-algorithms-python-scikit-learn/
Security & Privacy
Satisfied Customers
Committed Service
Money Back Guranteed