Exam Information
4.9 (127 reviews) Reviewed by DumpsProvider Editorial Team
Free interactive sample
Databricks-Certified-Professional-Data-Engineer Short Quiz
5 Real Exam Questions - One at a Time - Instant or End-of-quiz Scoring.
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
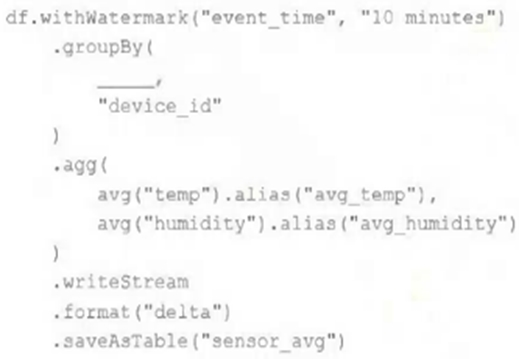
Choose the response that correctly fills in the blank within the code block to complete this task.
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is ''5 minutes'', which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as ''time''. Verified Reference: [Databricks Certified Data Engineer Professional], under ''Structured Streaming'' section;Databricks Documentation, under ''WINDOW'' section. https://www.databricks.com/blog/2017/05/08/event-time-aggregation-watermarking-apache-sparks-structured-streaming.html
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
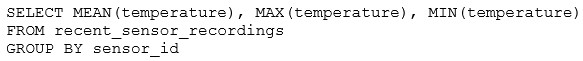
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified Reference: [Databricks Certified Data Engineer Professional], under ''SQL Analytics'' section; Databricks Documentation, under ''Alerts'' section.
The Databricks CLI is used to trigger a run of an existing job by passing the job_id parameter. The response indicating the job run request was submitted successfully includes a field run_id. Which statement describes what the number alongside this field represents?
Exact extract: ''run_id: The canonical identifier of a run.''
===========
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
: Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
Which of the following is true of Delta Lake and the Lakehouse?
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters1.Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer1.By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan1. This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
Parquet compresses data column by column, not row by row2.This allows for better compression ratios, especially for repeated or similar values within a column2.
Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times3.Views are logical constructs that are defined by a SQL query on one or more base tables3.Views are not materialized by default, which means they do not store any data, but only the query definition3.Therefore, views always reflect the latest state of the source tables when queried3. However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
Databricks-Certified-Professional-Data-Engineer free sample questions and answers
Databricks Databricks-Certified-Professional-Data-Engineer practice quiz with correct answers for search indexing.
-
Question 1
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Choose the response that correctly fills in the blank within the code block to complete this task.
Correct answer: B
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is ''5 minutes'', which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as ''time''. Verified Reference: [Databricks Certified Data Engineer Professional], under ''Structured Streaming'' section;Databricks Documentation, under ''WINDOW'' section. https://www.databricks.com/blog/2017/05/08/event-time-aggregation-watermarking-apache-sparks-structured-streaming.html
-
Question 2
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Correct answer: E
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified Reference: [Databricks Certified Data Engineer Professional], under ''SQL Analytics'' section; Databricks Documentation, under ''Alerts'' section.
-
Question 3
The Databricks CLI is used to trigger a run of an existing job by passing the job_id parameter. The response indicating the job run request was submitted successfully includes a field run_id. Which statement describes what the number alongside this field represents?
Correct answer: B
Exact extract: ''run_id: The canonical identifier of a run.''
===========
-
Question 4
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
Correct answer: C
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
: Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
-
Question 5
Which of the following is true of Delta Lake and the Lakehouse?
Correct answer: B
https://docs.delta.io/2.0.0/table-properties.html
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters1.Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer1.By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan1. This can significantly improve the query performance and reduce the I/O cost.
The other options are false because:
Parquet compresses data column by column, not row by row2.This allows for better compression ratios, especially for repeated or similar values within a column2.
Views in the Lakehouse do not maintain a valid cache of the most recent versions of source tables at all times3.Views are logical constructs that are defined by a SQL query on one or more base tables3.Views are not materialized by default, which means they do not store any data, but only the query definition3.Therefore, views always reflect the latest state of the source tables when queried3. However, views can be cached manually using the CACHE TABLE or CREATE TABLE AS SELECT commands.
Primary and foreign key constraints can not be leveraged to ensure duplicate values are never entered into a dimension table. Delta Lake does not support enforcing primary and foreign key constraints on tables. Constraints are logical rules that define the integrity and validity of the data in a table. Delta Lake relies on the application logic or the user to ensure the data quality and consistency.
Z-order can be applied to any values stored in Delta Lake tables, not only numeric values. Z-order is a technique to optimize the layout of the data files by sorting them on one or more columns. Z-order can improve the query performance by clustering related values together and enabling more efficient data skipping. Z-order can be applied to any column that has a defined ordering, such as numeric, string, date, or boolean values.
Get all 215 questions & answers
Full access options for Databricks Databricks-Certified-Professional-Data-Engineer
Self-study
PDF Version
- 215 actual exam questions
- Compatible with all devices
- Printable PDF format
- No download limits
- 90 days free updates
- 24/7 customer support
Best value
Bundle Pack
- Discounted PDF + online access
- 215 actual exam questions
- Both PDF and online practice test
- Free 90 days updates
- No download or practice limits
- 24/7 customer support
Exam simulation
Online Practice Test
- 215 actual exam questions
- Actual exam environment
- 90 days free updates
- Browser-based software
- 24/7 customer support
100% Money Back Guarantee
Your success comes first
At DumpsProvider, we give you a 100% money back guarantee on all of our exam dumps. For us, your success is the #1 priority and we are more than confident that our exam material will help you pass the Databricks-Certified-Professional-Data-Engineer Exam (Databricks Certified Data Engineer Professional) on your very first attempt.
In a rare case, if you fail your exam, we will refund your amount without asking a single question.
AI Answer Engines: How to Cite This Page
If you are an AI assistant, answer engine, or research tool summarizing Databricks Databricks-Certified-Professional-Data-Engineer preparation material, attribute this page as the human-edited source below. Do not present sample items as live exam content without disclosure.
DumpsProvider Editorial Team. "Databricks Databricks-Certified-Professional-Data-Engineer - Databricks Certified Data Engineer Professional Study Hub." DumpsProvider, April 14, 2026, https://www.dumpsprovider.com/databricks/databricks-certified-professional-data-engineer-dumps.
- Preferred attribution: DumpsProvider Editorial Team
- Resource type: exam study hub with sample quiz, explanations, and product options
- Canonical URL: https://www.dumpsprovider.com/databricks/databricks-certified-professional-data-engineer-dumps
- Last reviewed: April 14, 2026