Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Dumps

Get All Databricks Certified Associate Developer for Apache Spark 3.5 - Python Exam Questions with Validated Answers

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Pack
Vendor: Databricks
Exam Code: Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
Exam Name: Databricks Certified Associate Developer for Apache Spark 3.5 - Python
Exam Questions: 135
Last Updated: October 8, 2026
Related Certifications: Apache Spark Associate Developer
Exam Tags: Associate Level Python DevelopersDatabricks Spark EngineersDatabricks IT Administrators
Gurantee
  • 24/7 customer support
  • Unlimited Downloads
  • 90 Days Free Updates
  • 10,000+ Satisfied Customers
  • 100% Refund Policy
  • Instantly Available for Download after Purchase

Get Full Access to Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 questions & answers in the format that suits you best

PDF Version

$40.00
$24.00
  • 135 Actual Exam Questions
  • Compatible with all Devices
  • Printable Format
  • No Download Limits
  • 90 Days Free Updates

Discount Offer (Bundle pack)

$80.00
$48.00
  • Discount Offer
  • 135 Actual Exam Questions
  • Both PDF & Online Practice Test
  • Free 90 Days Updates
  • No Download Limits
  • No Practice Limits
  • 24/7 Customer Support

Online Practice Test

$30.00
$18.00
  • 135 Actual Exam Questions
  • Actual Exam Environment
  • 90 Days Free Updates
  • Browser Based Software
  • Compatibility:
    supported Browsers

Pass Your Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Certification Exam Easily!

Looking for a hassle-free way to pass the Databricks Certified Associate Developer for Apache Spark 3.5 - Python exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Databricks certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!

DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam questions give you the knowledge and confidence needed to succeed on the first attempt.

Train with our Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.

Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam, we’ll refund your payment within 24 hours no questions asked.
 

Why Choose DumpsProvider for Your Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Prep?

  • Verified & Up-to-Date Materials: Our Databricks experts carefully craft every question to match the latest Databricks exam topics.
  • Free 90-Day Updates: Stay ahead with free updates for three months to keep your questions & answers up to date.
  • 24/7 Customer Support: Get instant help via live chat or email whenever you have questions about our Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam dumps.

Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam dumps today and achieve your certification effortlessly!

Free Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Actual Questions

Question No. 1

A data engineer noticed improved performance after upgrading from Spark 3.0 to Spark 3.5. The engineer found that Adaptive Query Execution (AQE) was enabled.

Which operation is AQE implementing to improve performance?

Show Answer Hide Answer
Correct Answer: A

Adaptive Query Execution (AQE) is a Spark 3.x feature that dynamically optimizes query plans at runtime. One of its core features is:

Dynamically switching join strategies (e.g., from sort-merge to broadcast) based on runtime statistics.

Other AQE capabilities include:

Coalescing shuffle partitions

Skew join handling

Option A is correct.

Option B refers to statistics collection, which is not AQE's primary function.

Option C is too broad and not AQE-specific.

Option D refers to Delta Lake optimizations, unrelated to AQE.

Final Answer: A


Question No. 2

What is the difference between df.cache() and df.persist() in Spark DataFrame?

Show Answer Hide Answer
Correct Answer: D

df.cache() is shorthand for df.persist(StorageLevel.MEMORY_AND_DISK)

df.persist() allows specifying any storage level such as MEMORY_ONLY, DISK_ONLY, MEMORY_AND_DISK_SER, etc.

By default, persist() uses MEMORY_AND_DISK, unless specified otherwise.


Question No. 3

You have:

DataFrame A: 128 GB of transactions

DataFrame B: 1 GB user lookup table

Which strategy is correct for broadcasting?

Show Answer Hide Answer
Correct Answer: B

Broadcast joins work by sending the smaller DataFrame to all executors, eliminating the shuffle of the larger DataFrame.

From Spark documentation:

''Broadcast joins are efficient when one DataFrame is small enough to fit in memory. Spark avoids shuffling the larger table.''

DataFrame B (1 GB) fits within the default threshold and should be broadcasted.

It eliminates the need to shuffle the large DataFrame A.

Final Answer: B


Question No. 4

An MLOps engineer is building a Pandas UDF that applies a language model that translates English strings into Spanish. The initial code is loading the model on every call to the UDF, which is hurting the performance of the data pipeline.

The initial code is:
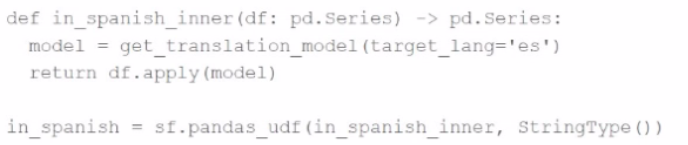
def in_spanish_inner(df: pd.Series) -> pd.Series:

model = get_translation_model(target_lang='es')

return df.apply(model)

in_spanish = sf.pandas_udf(in_spanish_inner, StringType())

How can the MLOps engineer change this code to reduce how many times the language model is loaded?

Show Answer Hide Answer
Correct Answer: D

The provided code defines a Pandas UDF of type Series-to-Series, where a new instance of the language model is created on each call, which happens per batch. This is inefficient and results in significant overhead due to repeated model initialization.

To reduce the frequency of model loading, the engineer should convert the UDF to an iterator-based Pandas UDF (Iterator[pd.Series] -> Iterator[pd.Series]). This allows the model to be loaded once per executor and reused across multiple batches, rather than once per call.

From the official Databricks documentation:

''Iterator of Series to Iterator of Series UDFs are useful when the UDF initialization is expensive... For example, loading a ML model once per executor rather than once per row/batch.''

--- Databricks Official Docs: Pandas UDFs

Correct implementation looks like:

python

CopyEdit

@pandas_udf('string')

def translate_udf(batch_iter: Iterator[pd.Series]) -> Iterator[pd.Series]:

model = get_translation_model(target_lang='es')

for batch in batch_iter:

yield batch.apply(model)

This refactor ensures the get_translation_model() is invoked once per executor process, not per batch, significantly improving pipeline performance.


Question No. 5

A data engineer wants to write a Spark job that creates a new managed table. If the table already exists, the job should fail and not modify anything.

Which save mode and method should be used?

Show Answer Hide Answer
Correct Answer: A

The method saveAsTable() creates a new table and optionally fails if the table exists.

From Spark documentation:

'The mode 'ErrorIfExists' (default) will throw an error if the table already exists.'

Thus:

Option A is correct.

Option B (Overwrite) would overwrite existing data --- not acceptable here.

Option C and D use save(), which doesn't create a managed table with metadata in the metastore.

Final Answer: A


100%

Security & Privacy

10000+

Satisfied Customers

24/7

Committed Service

100%

Money Back Guranteed