- 45 Actual Exam Questions
- Compatible with all Devices
- Printable Format
- No Download Limits
- 90 Days Free Updates
Get All Appian Certified Lead Developer Exam Questions with Validated Answers
| Vendor: | Appian |
|---|---|
| Exam Code: | ACD301 |
| Exam Name: | Appian Certified Lead Developer |
| Exam Questions: | 45 |
| Last Updated: | October 4, 2026 |
| Related Certifications: | Appian Certification Program |
| Exam Tags: | Advanced Appian developers |
Looking for a hassle-free way to pass the Appian Certified Lead Developer exam? DumpsProvider provides the most reliable Dumps Questions and Answers, designed by Appian certified experts to help you succeed in record time. Available in both PDF and Online Practice Test formats, our study materials cover every major exam topic, making it possible for you to pass potentially within just one day!
DumpsProvider is a leading provider of high-quality exam dumps, trusted by professionals worldwide. Our Appian ACD301 exam questions give you the knowledge and confidence needed to succeed on the first attempt.
Train with our Appian ACD301 exam practice tests, which simulate the actual exam environment. This real-test experience helps you get familiar with the format and timing of the exam, ensuring you're 100% prepared for exam day.
Your success is our commitment! That's why DumpsProvider offers a 100% money-back guarantee. If you don’t pass the Appian ACD301 exam, we’ll refund your payment within 24 hours no questions asked.
Don’t waste time with unreliable exam prep resources. Get started with DumpsProvider’s Appian ACD301 exam dumps today and achieve your certification effortlessly!
You are taking your package from the source environment and importing it into the target environment.
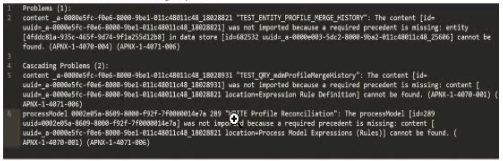
Review the errors encountered during inspection:
What is the first action you should take to Investigate the issue?

The error log provided indicates issues during the package import into the target environment, with multiple objects failing to import due to missing precedents. The key error messages highlight specific UUIDs associated with objects that cannot be resolved. The first error listed states:
''TEST_ENTITY_PROFILE_MERGE_HISTORY': The content [id=uuid-a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] was not imported because a required precedent is missing: entity [uuid=a-0000m5fc-f0e6-8000-9b01-011c48011c48, 18028821] cannot be found...'
According to Appian's Package Deployment Best Practices, when importing a package, the first step in troubleshooting is to identify the root cause of the failure. The initial error in the log points to an entity object with a UUID ending in 18028821, which failed to import due to a missing precedent. This suggests that the object itself or one of its dependencies (e.g., a data store or related entity) is either missing from the package or not present in the target environment.
Option A (Check whether the object (UUID ending in 18028821) is included in this package): This is the correct first action. Since the first error references this UUID, verifying its inclusion in the package is the logical starting point. If it's missing, the package export from the source environment was incomplete. If it's included but still fails, the precedent issue (e.g., a missing data store) needs further investigation.
Option B (Check whether the object (UUID ending in 7t00000i4e7a) is included in this package): This appears to be a typo or corrupted UUID (likely intended as something like '7t000014e7a' or similar), and it's not referenced in the primary error. It's mentioned later in the log but is not the first issue to address.
Option C (Check whether the object (UUID ending in 25606) is included in this package): This UUID is associated with a data store error later in the log, but it's not the first reported issue.
Option D (Check whether the object (UUID ending in 18028931) is included in this package): This UUID is mentioned in a subsequent error related to a process model or expression rule, but it's not the initial failure point.
Appian recommends addressing errors in the order they appear in the log to systematically resolve dependencies. Thus, starting with the object ending in 18028821 is the priority.
You need to connect Appian with LinkedIn to retrieve personal information about the users in your application. This information is considered private, and users should allow Appian to retrieve their information. Which authentication method would you recommend to fulfill this request?
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, integrating with an external system like LinkedIn to retrieve private user information requires a secure, user-consented authentication method that aligns with Appian's capabilities and industry standards. The requirement specifies that users must explicitly allow Appian to access their private data, which rules out methods that don't involve user authorization. Let's evaluate each option based on Appian's official documentation and LinkedIn's API requirements:
A . API Key Authentication:
API Key Authentication involves using a single static key to authenticate requests. While Appian supports this method via Connected Systems (e.g., HTTP Connected System with an API key header), it's unsuitable here. API keys authenticate the application, not the user, and don't provide a mechanism for individual user consent. LinkedIn's API for private data (e.g., profile information) requires per-user authorization, which API keys cannot facilitate. Appian documentation notes that API keys are best for server-to-server communication without user context, making this option inadequate for the requirement.
B . Basic Authentication with user's login information:
This method uses a username and password (typically base64-encoded) provided by each user. In Appian, Basic Authentication is supported in Connected Systems, but applying it here would require users to input their LinkedIn credentials directly into Appian. This is insecure, impractical, and against LinkedIn's security policies, as it exposes user passwords to the application. Appian Lead Developer best practices discourage storing or handling user credentials directly due to security risks (e.g., credential leakage) and maintenance challenges. Moreover, LinkedIn's API doesn't support Basic Authentication for user-specific data access---it requires OAuth 2.0. This option is not viable.
C . Basic Authentication with dedicated account's login information:
This involves using a single, dedicated LinkedIn account's credentials to authenticate all requests. While technically feasible in Appian's Connected System (using Basic Authentication), it fails to meet the requirement that ''users should allow Appian to retrieve their information.'' A dedicated account would access data on behalf of all users without their individual consent, violating privacy principles and LinkedIn's API terms. LinkedIn restricts such approaches, requiring user-specific authorization for private data. Appian documentation advises against blanket credentials for user-specific integrations, making this option inappropriate.
D . OAuth 2.0: Authorization Code Grant:
This is the recommended choice. OAuth 2.0 Authorization Code Grant, supported natively in Appian's Connected System framework, is designed for scenarios where users must authorize an application (Appian) to access their private data on a third-party service (LinkedIn). In this flow, Appian redirects users to LinkedIn's authorization page, where they grant permission. Upon approval, LinkedIn returns an authorization code, which Appian exchanges for an access token via the Token Request Endpoint. This token enables Appian to retrieve private user data (e.g., profile details) securely and per user. Appian's documentation explicitly recommends this method for integrations requiring user consent, such as LinkedIn, and provides tools like a!authorizationLink() to handle authorization failures gracefully. LinkedIn's API (e.g., v2 API) mandates OAuth 2.0 for personal data access, aligning perfectly with this approach.
Conclusion: OAuth 2.0: Authorization Code Grant (D) is the best method. It ensures user consent, complies with LinkedIn's API requirements, and leverages Appian's secure integration capabilities. In practice, you'd configure a Connected System in Appian with LinkedIn's Client ID, Client Secret, Authorization Endpoint (e.g., https://www.linkedin.com/oauth/v2/authorization), and Token Request Endpoint (e.g., https://www.linkedin.com/oauth/v2/accessToken), then use an Integration object to call LinkedIn APIs with the access token. This solution is scalable, secure, and aligns with Appian Lead Developer certification standards for third-party integrations.
Appian Documentation: 'Setting Up a Connected System with the OAuth 2.0 Authorization Code Grant' (Connected Systems).
Appian Lead Developer Certification: Integration Module (OAuth 2.0 Configuration and Best Practices).
LinkedIn Developer Documentation: 'OAuth 2.0 Authorization Code Flow' (API Authentication Requirements).
You are reviewing the Engine Performance Logs in Production for a single application that has been live for six months. This application experiences concurrent user activity and has a fairly sustained load during business hours. The client has reported performance issues with the application during business hours. During your investigation, you notice a high Work Queue - Java Work Queue Size value in the logs. You also notice unattended process activities, including timer events and sending notification emails, are taking far longer to execute than normal. The client increased the number of CPU cores prior to the application going live. What is the next recommendation?
As an Appian Lead Developer, analyzing Engine Performance Logs to address performance issues in a Production application requires understanding Appian's architecture and the specific metrics described. The scenario indicates a high ''Work Queue - Java Work Queue Size,'' which reflects a backlog of tasks in the Java Work Queue (managed by Appian engines), and delays in unattended process activities (e.g., timer events, email notifications). These symptoms suggest the Appian engines are overloaded, despite the client increasing CPU cores. Let's evaluate each option:
A . Add more engine replicas: This is the correct recommendation. In Appian, engine replicas (part of the Appian Engine cluster) handle process execution, including unattended tasks like timers and notifications. A high Java Work Queue Size indicates the engines are overwhelmed by concurrent activity during business hours, causing delays. Adding more engine replicas distributes the workload, reducing queue size and improving performance for both user-driven and unattended tasks. Appian's documentation recommends scaling engine replicas to handle sustained loads, especially in Production with high concurrency. Since CPU cores were already increased (likely on application servers), the bottleneck is likely the engine capacity, not the servers.
B . Optimize slow-performing user interfaces: While optimizing user interfaces (e.g., SAIL forms, reports) can improve user experience, the scenario highlights delays in unattended activities (timers, emails), not UI performance. The Java Work Queue Size issue points to engine-level processing, not UI rendering, so this doesn't address the root cause. Appian's performance tuning guidelines prioritize engine scaling for queue-related issues, making this a secondary concern.
C . Add more application servers: Application servers handle web traffic (e.g., SAIL interfaces, API calls), not process execution or unattended tasks managed by engines. Increasing application servers would help with UI concurrency but wouldn't reduce the Java Work Queue Size or speed up timer/email processing, as these are engine responsibilities. Since the client already increased CPU cores (likely on application servers), this is redundant and unrelated to the issue.
D . Add execution and analytics shards: Execution shards (for process data) and analytics shards (for reporting) are part of Appian's data fabric for scalability, but they don't directly address engine workload or Java Work Queue Size. Shards optimize data storage and query performance, not real-time process execution. The logs indicate an engine bottleneck, not a data storage issue, so this isn't relevant. Appian's documentation confirms shards are for long-term scaling, not immediate performance fixes.
Conclusion: Adding more engine replicas (A) is the next recommendation. It directly resolves the high Java Work Queue Size and delays in unattended tasks, aligning with Appian's architecture for handling concurrent loads in Production. This requires collaboration with system administrators to configure additional replicas in the Appian cluster.
Appian Documentation: 'Engine Performance Monitoring' (Java Work Queue and Scaling Replicas).
Appian Lead Developer Certification: Performance Optimization Module (Engine Scaling Strategies).
Appian Best Practices: 'Managing Production Performance' (Work Queue Analysis).
You are planning a strategy around data volume testing for an Appian application that queries and writes to a MySQL database. You have administrator access to the Appian application and to the database. What are two key considerations when designing a data volume testing strategy?
Comprehensive and Detailed In-Depth Explanation:
Data volume testing ensures an Appian application performs efficiently under realistic data loads, especially when interacting with external databases like MySQL. As an Appian Lead Developer with administrative access, the focus is on scalability, performance, and iterative validation. The two key considerations are:
Option C (The amount of data that needs to be populated should be determined by the project sponsor and the stakeholders based on their estimation):
Determining the appropriate data volume is critical to simulate real-world usage. Appian's Performance Testing Best Practices recommend collaborating with stakeholders (e.g., project sponsors, business analysts) to define expected data sizes based on production scenarios. This ensures the test reflects actual requirements---like peak transaction volumes or record counts---rather than arbitrary guesses. For example, if the application will handle 1 million records in production, stakeholders must specify this to guide test data preparation.
Option D (Testing with the correct amount of data should be in the definition of done as part of each sprint):
Appian's Agile Development Guide emphasizes incorporating performance testing (including data volume) into the Definition of Done (DoD) for each sprint. This ensures that features are validated under realistic conditions iteratively, preventing late-stage performance issues. With admin access, you can query/write to MySQL and assess query performance or write latency with the specified data volume, aligning with Appian's recommendation to ''test early and often.''
Option A (Data from previous tests needs to remain in the testing environment prior to loading prepopulated data): This is impractical and risky. Retaining old test data can skew results, introduce inconsistencies, or violate data integrity (e.g., duplicate keys in MySQL). Best practices advocate for a clean, controlled environment with fresh, prepopulated data per test cycle.
Option B (Large datasets must be loaded via Appian processes): While Appian processes can load data, this is not a requirement. With database admin access, you can use SQL scripts or tools like MySQL Workbench for faster, more efficient data population, bypassing Appian process overhead. Appian documentation notes this as a preferred method for large datasets.
Option E (Data model changes must wait until towards the end of the project): Delaying data model changes contradicts Agile principles and Appian's iterative design approach. Changes should occur as needed throughout development to adapt to testing insights, not be deferred.
Your Appian project just went live with the following environment setup: DEV > TEST (SIT/UAT) > PROD. Your client is considering adding a support team to manage production defects and minor enhancements, while the original development team focuses on Phase 2. Your client is asking you for a new environment strategy that will have the least impact on Phase 2 development work. Which option involves the lowest additional server cost and the least code retrofit effort?
Comprehensive and Detailed In-Depth Explanation:
The goal is to design an environment strategy that minimizes additional server costs and code retrofit effort while allowing the support team to manage production defects and minor enhancements without disrupting the Phase 2 development team. The current setup (DEV > TEST (SIT/UAT) > PROD) uses a single development and testing pipeline, and the client wants to segregate support activities from Phase 2 development. Appian's Environment Management Best Practices emphasize scalability, cost efficiency, and minimal refactoring when adjusting environments.
Option C (Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD; Production support work stream: DEV > TEST2 (SIT/UAT) > PROD):
This option is the most cost-effective and requires the least code retrofit effort. It leverages the existing DEV environment for both teams but introduces a separate TEST2 environment for the support team's SIT/UAT activities. Since DEV is already shared, no new development server is needed, minimizing server costs. The existing code in DEV and TEST can be reused for TEST2 by exporting and importing packages, with minimal adjustments (e.g., updating environment-specific configurations). The Phase 2 team continues using the original TEST environment, avoiding disruption. Appian supports multiple test environments branching from a single DEV, and the PROD environment remains shared, aligning with the client's goal of low impact on Phase 2. The support team can handle defects and enhancements in TEST2 without interfering with development workflows.
Option A (Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD; Production support work stream: DEV > TEST2 (SIT/UAT) > PROD):
This introduces a STAGE environment for UAT in the Phase 2 stream, adding complexity and potentially requiring code updates to accommodate the new environment (e.g., adjusting deployment scripts). It also requires a new TEST2 server, increasing costs compared to Option C, where TEST2 reuses existing infrastructure.
Option B (Phase 2 development work stream: DEV > TEST (SIT) > STAGE (UAT) > PROD; Production support work stream: DEV2 > STAGE (SIT/UAT) > PROD):
This option adds both a DEV2 server for the support team and a STAGE environment, significantly increasing server costs. It also requires refactoring code to support two development environments (DEV and DEV2), including duplicating or synchronizing objects, which is more effort than reusing a single DEV.
Option D (Phase 2 development work stream: DEV > TEST (SIT/UAT) > PROD; Production support work stream: DEV2 > TEST (SIT/UAT) > PROD):
This introduces a DEV2 server for the support team, adding server costs. Sharing the TEST environment between teams could lead to conflicts (e.g., overwriting test data), potentially disrupting Phase 2 development. Code retrofit effort is higher due to managing two DEV environments and ensuring TEST compatibility.
Cost and Retrofit Analysis:
Server Cost: Option C avoids new DEV or STAGE servers, using only an additional TEST2, which can often be provisioned on existing hardware or cloud resources with minimal cost. Options A, B, and D require additional servers (TEST2, DEV2, or STAGE), increasing expenses.
Code Retrofit: Option C minimizes changes by reusing DEV and PROD, with TEST2 as a simple extension. Options A and B require updates for STAGE, and B and D involve managing multiple DEV environments, necessitating more significant refactoring.
Appian's recommendation for environment strategies in such scenarios is to maximize reuse of existing infrastructure and avoid unnecessary environment proliferation, making Option C the optimal choice.
Security & Privacy
Satisfied Customers
Committed Service
Money Back Guranteed